🔍 Read the full analysis: Two Robotics AI Moves Raise One Question: Do Robots Need Their Own Models? on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
OpenAI confirmed to Fortune that it has reorganized its robotics teams, saying general-purpose models such as GPT-6 Astra can now be applied directly to robot control. Runway has taken a different approach with Praxis-1, a dedicated, open-weight model. Published results show a trade-off: GPT-6 Astra scored higher in one simulation test, while specialist models acted faster; the tests do not settle which approach will work best in real-world robots.
OpenAI has reorganized its robotics teams, moving researchers into its main research group and applied robotics and hardware teams into its Applied organization, while Runway has released Praxis-1, a model designed specifically for robots. The contrasting moves sharpen a question for robotics developers: can general-purpose AI models control robots effectively, or do robots need dedicated models built for faster action?
OpenAI confirmed the reorganization to Fortune, which reported the change on November 13. According to the outlet, the robotics researchers now report to Chief Research Officer Mark Chen, while applied robotics and hardware teams have moved to the Applied organization under President Greg Brockman. OpenAI’s spokesperson described the move as a commitment to robotics rather than a retreat. The company has not published its own announcement about the change.
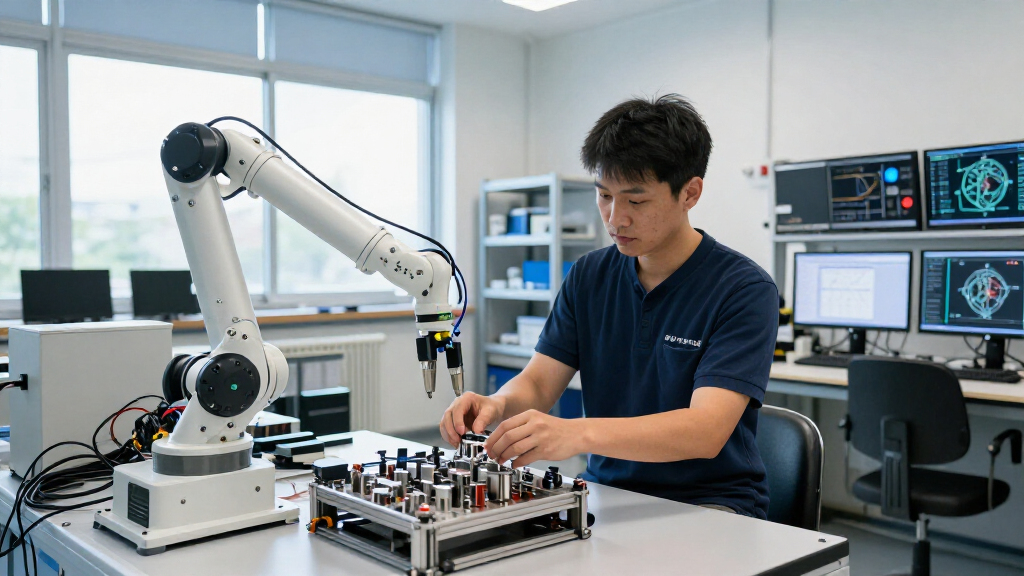
Runway released Praxis-1 two days before the report. It is a 27-billion-parameter “world action model,” with weights and fine-tuning code available under the Apache 2.0 license, which permits commercial use. On the RoboLab-120 benchmark, Praxis-1 scored 46.2%, the highest among the world action models and open-source robot models listed there, and fifth overall.
The results cited in the reporting point to a capability-versus-speed trade-off, not a settled winner. In an NVIDIA researchers’ simulation study, GPT-6 Astra achieved a 74.8% success rate on RoboLab-120 when used in an agentic setup, compared with 51.0% for the leading trained robot policy cited in the source material. But a direct GPT-6 Astra model call took an average of 18.56 seconds, with the simulation paused while it processed. Praxis-1 took about 0.55 to 0.6 seconds per call for 1.6 seconds of motion.
Robot control loop · explainer
Who decides the robot’s next move?
Every robot repeats one loop: cameras see, a model decides, the arm moves. The two bets in this story put a different kind of model into the decide step.
Option 1
A general model in the loop
Example: GPT-6 Astra in NVIDIA’s simulation study
18.56 s per model call on average in the direct set-up. Inference was 97.0% of the estimated episode time; the simulation paused while the model was thinking.
Option 2
A specialist robot model in the loop
Example: Runway’s Praxis-1, a world action model with open weights
About 0.55–0.6 s per call on one H100 server, and each call returns 1.6 s of motion. Needs fine-tuning data for each robot.
General model plans the next stepslow, outside the loop
Option 3 · illustrative
Both, in two layers
The idea Runway and the NVIDIA researchers both describe
Runway calls the two approaches “complementary”: an agent plans, a fast policy carries out each step. NVIDIA’s authors say the best way to combine them “remains an open question”.
Sources: NVIDIA Seattle Robotics Lab, “Astranomy” study of GPT-6 Astra, Oct 14, 2026 (simulation, direct set-up); Runway, Praxis-1 technical report, Nov 2026 (one H100 server). Loops and timelines are schematic; the two figures come from different set-ups, not from a head-to-head test.
Graphic: Powered by Thorsten Meyer AI
Speed and Capability Pull Apart
Robot control has to account for both whether a system can complete a task and how quickly it can respond. A model that performs well in a paused simulation may not be suitable for a robot that must react continuously to objects, people or changes in its surroundings. The reported 18.56-second average call time for GPT-6 Astra’s direct setup makes that distinction concrete, although the study does not establish how the system would perform under every real-time deployment condition.
Dedicated models such as Praxis-1 are designed to produce robot actions more quickly, and their open weights may let developers inspect, adapt and run them for particular uses. Runway also reported that, in its own test on one of its robots, GPT-6 Astra took 15.6 times longer than Praxis-1 to finish three tasks and cost 51 times more per completed task. That comparison is Runway’s result, not an independent evaluation; the source does not provide enough detail to treat it as a general measure across robots or tasks.
The organizational choices matter because they signal different ways to build robot intelligence. OpenAI is placing its robotics work alongside general-model research and applied teams; Runway is making a specialized model available for others to use. The benchmark and company test results leave room for a third path: general models could handle planning or complex reasoning while faster specialist policies execute movements.
Products Worth Considering

Apple Watch Series 12 GPS 42mm
DJI Mini 5 Pro Fly More Combo with DJI RC 2

Bose QuietComfort Wireless Bluetooth Headphones – Active Over‑Ear Noise Cancelling with Mic, USB‑C Charging, Deep Bass, up to 24 h Playtime,
As an affiliate, we earn on qualifying purchases.
OpenAI’s explanation, as reported by Fortune, is that the company’s general-purpose frontier models, including GPT-6 Astra, have shown they can be applied directly to robotics. Earlier in the year, its researchers expected to build on video models such as Sora. OpenAI said the newer results prompted it to integrate robotics researchers with its main research organization. The company has also said it is developing a humanoid robot; Chief Executive Sam Altman has targeted a public demonstration in 2027.
This is the second time OpenAI has disbanded a stand-alone robotics team. It wound down an earlier team in 2020, then rebuilt robotics research in 2024 and partnered with humanoid-robot maker Figure. Figure said in February 2025 that it would develop its own robot AI, ending that partnership. The current change comes as OpenAI faces pressure to control costs, a business backdrop noted by Fortune; the reason OpenAI gave for the reorganization was the progress it sees in general-purpose models.
The NVIDIA researchers’ study, published October 14 as a CoRL 2026 late-breaking result, evaluated GPT-6 Astra as a “native robot policy.” It supplied the model with camera images, information about the robot and a control interface, without robot-specific training. RoboLab-120 is a simulation benchmark covering 120 tabletop tasks for one robot arm. In the study, the direct setup scored 66.3%; the agentic setup scored 74.8%; and a setup in which Astra reviewed actions from a trained policy scored 66.5%. Those figures describe performance in the benchmark, not established success rates for robots operating in everyday environments.
“The two approaches are complementary.”
— Runway
Simulation Results Leave Gaps
The available results do not establish whether GPT-6 Astra or Praxis-1 is more capable across real-world robots, tasks and operating conditions. RoboLab-120 is a simulation benchmark, and Runway’s comparison used one of its own robots on three tasks. The source material does not provide a matched, independent evaluation that tests both systems across a broad set of hardware and conditions.
It is also unclear how much the different systems’ results depend on their setup. GPT-6 Astra’s 74.8% figure came from an agentic configuration with persistent history and additional tools; its direct-policy result was 66.3%. The reported time per call applies to the direct setup and should not be treated as a universal speed measurement for every way of deploying the model. OpenAI has not released a statement of its own with further details about the reorganization, staffing or plans for robotics products.
More Tests Will Shape the Debate
The next useful evidence would be independent, matched tests that measure both task success and response time on physical robots, with the same tasks, hardware and operating conditions. Further reporting or an OpenAI statement could also clarify how the reorganized teams will work together and whether the company plans to publish robotics evaluations or demonstrations. OpenAI has targeted a public demonstration of its humanoid robot in 2027, but the available reporting does not say when the company will release more technical details.
For now, Praxis-1 gives developers an openly licensed specialist model to examine and adapt, while OpenAI’s move places robotics inside organizations working on its general models and applied systems. Whether those paths converge, or remain distinct, depends on evidence beyond the benchmark scores currently cited.
Key Questions
What did OpenAI change?
According to Fortune, OpenAI moved its robotics researchers to the main research group under Mark Chen and its applied robotics and hardware teams to the Applied organization under Greg Brockman. OpenAI confirmed the change to the outlet but has not published its own announcement.
What is Runway’s Praxis-1?
Praxis-1 is a 27-billion-parameter model designed for robot actions. Runway released its weights and fine-tuning code under the Apache 2.0 license, which permits commercial use.
Which model performed better on RoboLab-120?
GPT-6 Astra scored 74.8% in the NVIDIA study’s agentic setup. Praxis-1 scored 46.2%. The results come from different reported evaluations and do not by themselves establish which model is better across real robots or tasks.
Why might a robot use a specialist model?
The reported tests suggest specialist models can produce actions faster: Praxis-1 took about 0.55 to 0.6 seconds per call for 1.6 seconds of motion, while a direct GPT-6 Astra call averaged 18.56 seconds in the cited simulation study. Those timings depend on the test setup and are not a universal comparison.
Could general and specialist models work together?
Possibly. Runway called the approaches complementary, and the NVIDIA study also tested a setup in which GPT-6 Astra reviewed actions proposed by a trained robot policy. The available evidence does not show which combined design, if any, will work best in deployed robots.
Source: ThorstenMeyerAI.com