🔍 Read the full analysis: Inside The AI Process That Recognizes A Handwritten 7 on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
ThorstenMeyerAI.com published an explainer on November 8, 2026, tracing how a feedforward neural network can classify an image of a handwritten seven. It describes the arithmetic inside each layer, demonstrates how one bias can change a tiny network’s output, and counts 109,386 parameters in a small digit reader.
ThorstenMeyerAI.com published an explainer on November 8 showing how a neural network can classify a handwritten seven by passing image values through layers of arithmetic. The report illustrates the process with a small, hand-designed network and says a digit-reading model with its described architecture contains 109,386 parameters—the weights and biases that training adjusts.
For its example, the explainer represents a 28-by-28 grayscale image as 784 pixel values. An input layer holds those values and passes them forward; it does not perform the transformations attributed to the network’s hidden layers. Each hidden neuron multiplies inputs by learned weights, adds a bias, and applies an activation function. The resulting values become the next layer’s inputs.
The final layer in the example produces 10 scores, one for each digit. The predicted digit is the one with the highest score. The source describes this as a multilayer perceptron, or MLP, a feedforward network composed of dense layers in which each unit connects to the units in the next layer.
To make the mechanics tangible, the article builds a separate nine-number network for XOR, a function that returns one when two input bits differ. It then changes one output bias, from −2 to −1. Under the article’s specified step activation, that adjustment makes the network return one for all four possible input pairs. The demonstration is a simplified illustration, not a claim that changing one number in a trained image classifier would have an equally simple or predictable effect.
Infographic 01 · One bias, two behaviors
A network you can run by hand
Two hidden neurons check "at least one bit is on" and "at most one bit is on". The output neuron needs both. Change its bias and it needs only one.
Move the output bias from −2 to −1 and the network stops computing XOR: it returns 1 for all four inputs.
The whole network
Hidden 1: step( x₁ + x₂ − 1 )
Hidden 2: step(−x₁ − x₂ + 1 )
Output:   step( h₁ + h₂ − 2 )
step: 1 if the total is zero or greater, otherwise 0. Nine numbers in total: six in the hidden layer, three in the output neuron.
All four inputs
Hidden outputs and the final output with the original and the changed bias
| Input | At least one | At most one | Output, bias −2 | Output, bias −1 |
|---|---|---|---|---|
| 0, 0 | 0 | 1 | 0 | 1 |
| 0, 1 | 1 | 1 | 1 | 1 |
| 1, 0 | 1 | 1 | 1 | 1 |
| 1, 1 | 1 | 0 | 0 | 1 |
Sources: own arithmetic, checked with a script · the XOR example as in Goodfellow, Bengio, Courville: Deep Learning, ch. 6.
Powered by Thorsten Meyer AI
Why Pixel Connections Add Up
The parameter count helps explain why neural networks can be difficult to inspect, even when each operation is straightforward. In the described digit reader, about 92% of the 109,386 parameters are in the first layer. That concentration follows from the dense connections: each of the 784 pixel values connects to each of the layer’s 128 units, with additional parameters elsewhere in the model.
The source uses this arithmetic to connect a basic image-classification task with a broader research question: whether AI systems can inspect or edit another model’s internal parameters. It reports that MIT CSAIL researchers said an AI model read and edited other networks’ numbers. The source also reports one edit changed 0.016% of a language model’s weights and raised a math score from 7.9% to 48.1%. Those figures are presented in the source as a reported result, not as independently established evidence that such edits reliably improve models.
For readers, the distinction is useful: “black box” does not mean the computation is hidden at every level. A network’s operations can be written down, while understanding which combinations of many parameters produce a particular behavior remains difficult.
Products Worth Considering

LG UltraGear 25G590B-B 25-Inch Full HD 1000Hz Gaming Monitor
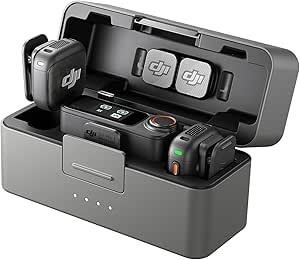
DJI Mic 3 (2 TX + 1 RX + Charging Case) Wireless Microphone
DJI Mini 5 Pro Fly More Combo Plus with DJI RC 2
As an affiliate, we earn on qualifying purchases.
From XOR to Digit Recognition
The XOR example is deliberately small enough to calculate by hand. Its two inputs can each be zero or one, and its output is one only when the inputs differ. The article’s hidden units test whether at least one input is on and whether at most one is on; together, those conditions identify the differing-input cases. A final unit combines the hidden outputs.
This construction is not the same as training a digit reader. The XOR network’s weights and biases are assigned by reasoning from the desired behavior, while a practical model normally learns its parameters during training. The network’s width and depth—the number of units and layers—are architectural choices made before training; weights and biases are learned values that can also be deliberately set in a toy example.
The explainer includes a video of about seven and a half minutes, described as a hand-drawn walkthrough from a handwritten seven to the XOR demonstration. Its page says the narration uses an AI voice clone of Thorsten Meyer. The source characterizes the separate MIT CSAIL account as a blog post with public logs, not a peer-reviewed paper.
“A neural network is arithmetic in layers.”
— ThorstenMeyerAI.com
What the Edit Result Establishes
The source does not provide enough detail to independently evaluate the reported language-model edit, including the model, the math benchmark, the evaluation setup, or whether the score change was reproduced. It says the result came from a blog post with public logs rather than a peer-reviewed paper, so the figures should be treated as claims reported by that source, not a settled research finding.
The article’s 109,386-parameter count applies to the particular small digit-reader architecture it describes. It is not a general count for image-recognition systems. The source also does not establish that the single-bias XOR intervention offers a direct method for changing a trained digit classifier; it presents the toy network to show, in a controlled case, how one parameter can alter behavior.
Further Checks on Model Editing
The source does not announce a new experiment, publication date, or planned follow-up. The immediate next step for readers interested in the reported model-editing result is to consult the linked public logs and the researchers’ underlying materials, then check whether a peer-reviewed paper or independent replication supplies additional evidence.
For the digit-recognition walkthrough, the video and accompanying explanation offer a route to follow the calculations layer by layer. The key distinction to keep in view is between a hand-built teaching example and the many learned parameters in a trained image model.
Key Questions
How does the network recognize a handwritten seven?
In the source’s example, a 28-by-28 image is represented by 784 pixel values. The network transforms those values through hidden layers and produces ten output scores; the digit with the highest score is its prediction.
Does the network contain a written rule for the shape of a seven?
The explainer says no explicit rule for the digit’s shape is written into its example. Instead, the model uses weights and biases learned during training to transform pixel values into output scores.
What does changing the bias demonstrate?
In the small XOR example, changing the output bias from −2 to −1 makes the network output one for every possible pair of input bits, given the stated step activation. It demonstrates how one parameter can change a toy network’s function; it does not show that a single edit will have the same effect in a trained digit reader.
How many parameters does the digit-reader example have?
The source gives a total of 109,386 parameters for its described small digit-reader architecture, with about 92% in the first layer. That number applies to the example, not to neural networks generally.
Is the reported AI model-editing result peer-reviewed?
According to ThorstenMeyerAI.com, the MIT CSAIL result it mentions appeared in a blog post with public logs, not a peer-reviewed paper. The source reports the score figures, but the information provided does not establish independent replication.
Source: ThorstenMeyerAI.com